How to Use LM Studio to turn your PC into an AI Server

 All screenshots: Matthew S. Smith
LM Studio is an amazing free app that lets you load and chat with AI large language models (LLMs) on your local PC, using local hardware. It's free to download for personal use and provides an easy-to-understand user interface. Micro Center dove into using LM Studio on your local PC previously; you can read that article here.
Using LM Studio to run LLMs on local hardware is great, but it's just the start. You can also use LM Studio to create a local AI server. Once active, you can use it to chat with an LLM running on your server from any device on your network. You can even use the LLM for code completion in apps like Visual Studio Code.
It's easy, too. This tutorial doesn't even require the command line interface, and we're sticking to apps that you can download and install in minutes. This tutorial works for Windows, MacOS, and Linux.
System requirements
Before diving in, let's cover the system requirements. Any modern Windows, Mac, or Linux computer can download LM Studio and run an LLM, but to be truly useful you're going to need specific hardware.
In most cases, a desktop or laptop graphics card will be required. You'll need a card with at least 8GB of VRAM, but 16GB or more is preferable. More intelligent models consume more memory, and increasing the context window also increases the memory footprint. So the more you have, the better.
Read more: Why VRAM and Memory Bandwidth are Key for Powering Local AI
Desktops or laptops with a unified memory architecture, like Apple Silicon Macs and Windows PCs with the AMD Ryzen AI Max+ 395, are an exception. These systems have a single pool of memory, so it's the total system memory that matters. At least 16GB of memory is still preferable.
For this tutorial, I'm running models on an AMD Radeon 7800 XT desktop graphics card with 16GB of memory.
Step 1: Download and install LM Studio
First things first: you need to download LM Studio. The website should automatically offer the version of LM Studio that works for your PC, but if it's wrong or doesn't appear, you can manually select the correct version here.
Installation is the same as any other application on your operating system of choice. On first start, the app will guide you through a quick tutorial. Select "Developer" when asked to choose your level of expertise.
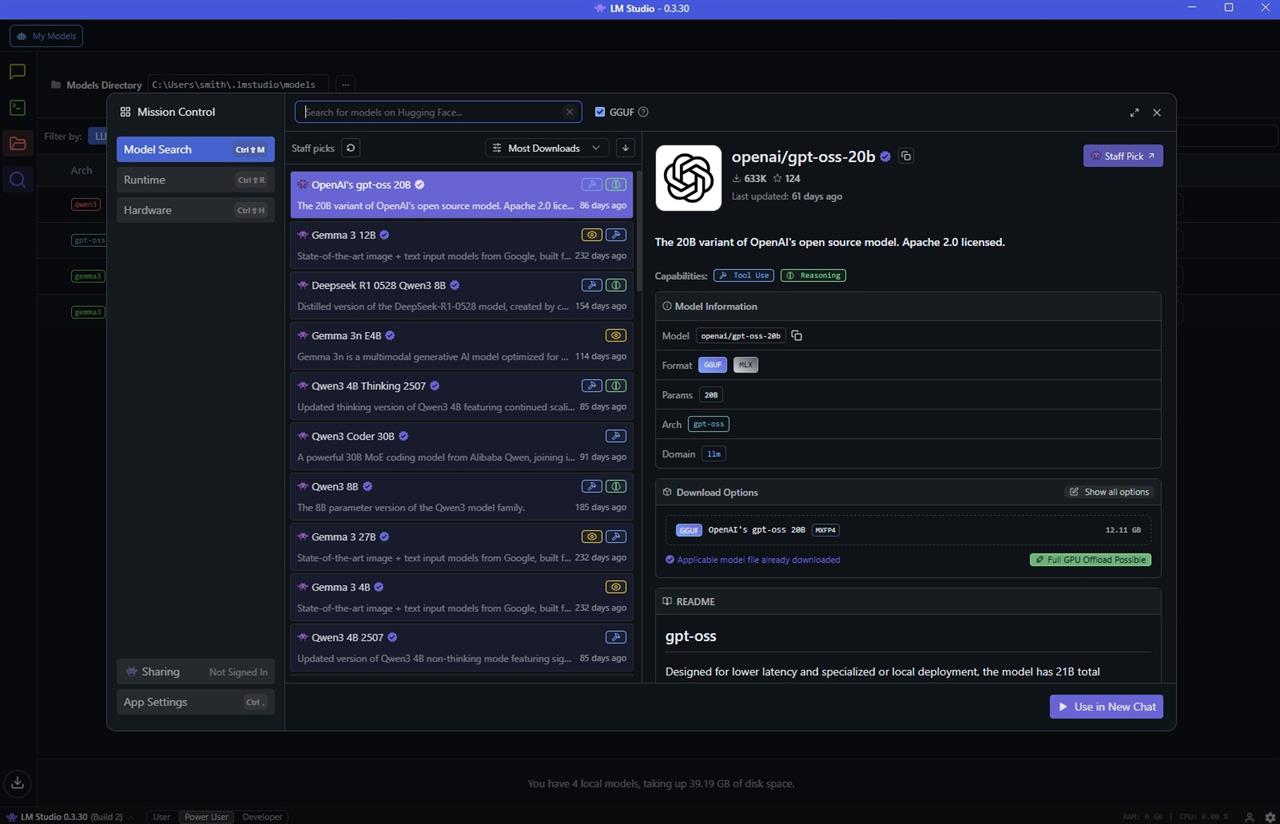
LM Studio will then prompt you to download a popular recent model like OpenAI's GPT-OSS-20B. It's a fine model but does require at least 16GB of memory to run well. If you have enough memory, download it (it's about 12GB, so that can take a few minutes). If you don't have enough memory, or you know you want to use another model, click Skip in the upper right hand corner of the app.
If you want to choose which local model to download first, click the purple Discover icon, which looks like a magnifying glass, in the menu bar on the left of the app. This will open a long list of models. Qwen3 4B 2507 is a good place to start as it's small, quick to download, and will fit comfortably within 8GB of memory (or even less).
Once you have a model downloaded, click the yellow Chat icon in the menu bar. Then look for the model load menu at the top of the app. Click "Select a model to load," and then choose the model you downloaded from the list. It will take a few seconds to load and prompt you once finished.
Now you can chat with the model in LM Studio.
Step 2: Enable the LM Studio server
Let's take this to the next level. We're going to make the LLM available to other devices on your network.
Click the green "Developer" icon, which looks like a command line interface. Near the top of the app you'll see "Status: Stopped," a toggle, and a Server Settings button. Click that button.
Flip the toggle beside "Serve on local network" so that it's on (green). I also recommend that you turn on Enable CORS. It's not always necessary, but some situations will require it.

Before you click out of this menu, note the Server Port. The default is 1234, but you can change it. I changed mine to 9999.
Now click the toggle by "Status: Stopped" so that it's on. This will activate the LM Studio server. You should see several messages, including Server Started, in the Developer Logs at the bottom of the window.

Once on, a new "Reachable at" message appears towards the upper right of the app. This will display the IP address of your server on your local network, as well as the port you selected. It should look something like "http://192.168.1.15:1234," where "1234" is the port you selected. Note it, because you're going to need that address to access the server from other devices.
The model you have loaded will also be visible. You can load a model, or switch to a new one, while the server is running. So if you didn't load a model earlier, do it now.
Step 3: Chat with your LM Studio server
Your first instinct might be to pop that address into your web browser. Unfortunately, it's not quite that simple. Doing that should display some JSON in your browser, but you can't do anything with it.
You're going to need a client that can communicate with the server and provide a chat interface. Strangely, LM Studio can't act as a client, not even with an LM Studio server. So you're going to need to download another app.
More advanced users might prefer Open WebUI, but since we're keeping things simple, I recommend AnythingLLM, which is available for Windows, MacOS, and Linux. As its name implies, AnythingLLM is a chat interface designed to work with any LLM. Most people use it to chat with online LLMs via the pay-as-you-go APIs provided by OpenAI, Google, Anthropic, and other LLM providers. But you can also use it to chat with your LM Studio server.
Once you have AnythingLLM installed and open, click on the wrench icon in the lower left corner. Expand the AI Providers menu, if it's not already, and click LLM.
This will open an LLM Provider selection interface. Click the drop-down box, which will open a search menu. Type and select LM Studio. Several sub-menus will appear.
Enter the address of your LM Studio server in the "LM Studio Base URL" field. Note that you need http:// at the beginning of the address and /v1 at the end. So the address should look something like "http://192.168.1.15:9999/v1".
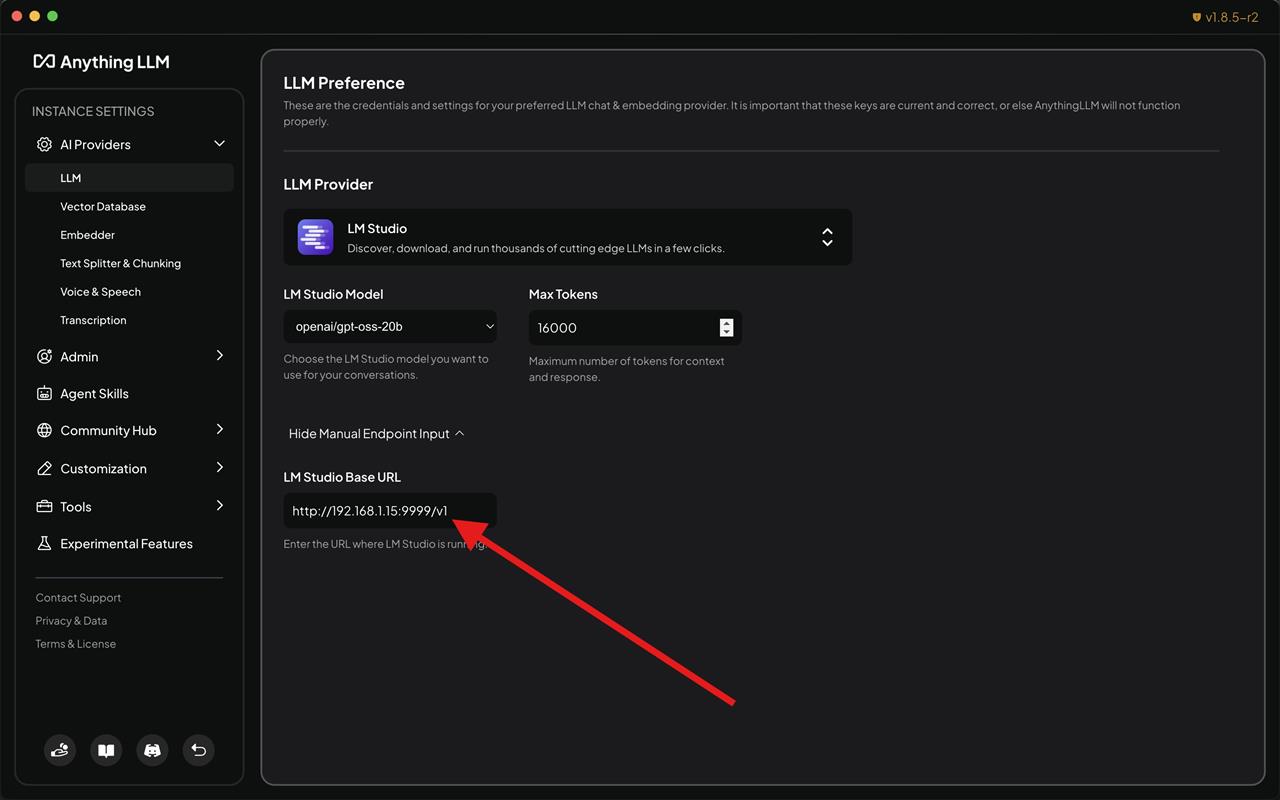
Once that's entered, select the model you want to use from the LM Studio Model drop-down menu and enter the maximum context window under Max Tokens (more tokens require more memory, so try to keep it around 8,000 or 16,000 tokens, unless you have way more than 16GB of memory dedicated to your LLM).
Now click the back button in the lower left and select a workspace in the left side menu. If no workspace is available, click the "+" button to add one. You should see a chat interface where you can chat with the LLM loaded on your LM Studio server.
You can also access the LM Studio server with a compatible smartphone app. AnythingLLM provides an Android app. It lacks an iOS app (for now), so iOS users should look at an app called 3sparks Chat. It's priced at $5.99 and worked well in my testing.
More on chat clients
An LM Studio server communicates with clients over OpenAI compatibility endpoints. That means any client able to communicate with them can be used with LM Studio. I used AnythingLLM in the example above, but you can also use Msty or Open WebUI, among dozens of other options.
Keep in mind that we're setting up a local AI server — but not one that's accessible outside your local network. That means you can't access it when away from home.
You could use port forwarding to get around that, but it's complicated and comes with privacy and security risks that are outside the scope of this tutorial. If you want to give it a go, though, I recommend this guide.
While this tutorial is focused on setting up a local AI server for your home network, the same steps apply if you only want to make the server accessible on the PC you're currently using. The only difference is that you'll leave the "Serve on Local Network" toggle unchecked. This will also change the address to a local IP address, such as http://127.0.0.1:9999.
Step 4: Using your LM Studio server beyond chat
While chat is the most obvious way to use an LM Studio server, you have other options. A wide variety of apps that use LLMs can potentially be used with an LM Studio server.
For example, you can connect to your LM Studio server for code completion in Microsoft Visual Studio Code. To do this, you'll need to install an AI code completion plug-in like Cline.
Once Cline is installed, open it and click the gear icon. Click the "API Provider" field and select LM Studio. Then enter your LM Studio's address in the "Use custom base URL" field. The Model drop-down menu will auto-populate. Click the Done button to return to Cline. You'll now be able to use your LM Studio server for code completion.

This is extremely powerful and applies to a huge variety of apps. You'll find plugins with the same capability available for Obsidian and Notion, for example. These can use your LM Studio server to generate text or parse documents in each app.
The only catch is that many of these apps require a large context window to be truly useful. That could be outside the capability of your local hardware, particularly if you have 16GB of available memory or less. For example, using Cline with GPT-OSS-20B was a problem on my AMD Radeon 7800 XT, as all but the most basic requests bumped the context window beyond what my hardware could reasonably handle.
Conclusion
That's it. You now have an LM Studio server running an LLM locally on your home network. Your chats will be private, no one will be able to train AI models on your data, and you won't have to pay a monthly subscription fee or API fees.
Running an LLM locally isn't perfect: the models you can run won't be as smart as the latest online models and are generally missing some features, like built-in web search.
But if you want an inexpensive, private, yet easy-to-use alternative to online LLMs from the world's tech giants, an LM Studio server is hard to beat.
More from MC News
- Run AI Locally: The Best LLMs for 8GB, 16GB, 32GB Memory and Beyond
- Quantization Explained: Why the Same LLM Gives Better Results on High-End Hardware
- Why VRAM and Memory Bandwidth are Key for Powering Local AI
- Keyboard 101: Intro to Computer Keyboards
- Fix It Yourself: Talking to iFixit on Why Repairable Tech Matters
- The Local LLM Your Laptop's Been Waiting For
- Gemma vs Qwen: Which Local AI is Best?
Matthew S. Smith is a prolific tech journalist, critic, product reviewer, and influencer from Portland, Oregon. Over 16 years covering tech he has reviewed thousands of PC laptops, desktops, monitors, and other consumer gadgets. Matthew also hosts Computer Gaming Yesterday, a YouTube channel dedicated to retro PC gaming, and covers the latest artificial intelligence research for IEEE Spectrum.


