

Can You Really Replace ChatGPT with a Local AI Workstation?

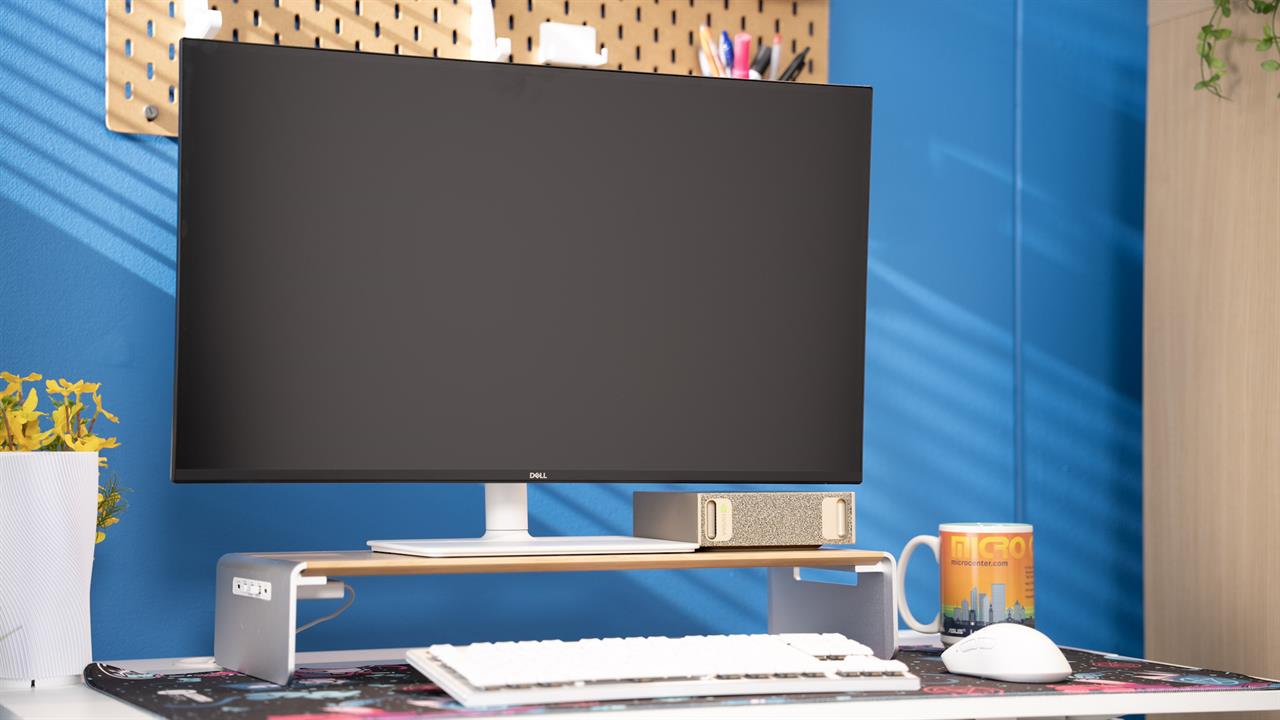
Photo: Jacob Bobo
The release of NVIDIA's DGX Spark, the first consumer-available AI workstation with Blackwell hardware, was a game changer for local AI. It's a powerful piece of AI hardware for its size and has 128GB of memory, a specification that feels even more impressive now than it did at release.
AI advances rapidly, however, as do the tools used with it. Several new open source models have released since then, most notably Alibaba's Qwen3.6, NVIDIA's Nemotron 3, and Google's Gemma 4.
Popular local LLM software has also improved. LM Studio, the client I most often use as a front-end for LLMs on my local machines, now offers a feature called LM Link that greatly simplifies serving a model hosted on an AI workstation to client machines.
Setup and ease of use
At their most basic level, all AI workstations powered by NVIDIA's GB10 are high-end Linux desktops. They ship pre-installed with a proprietary fork of Ubuntu called DGX OS. This includes a familiar Ubuntu desktop with the usual pre-installed apps.
Setup is simple. Just plug the workstation in, set up an account, and you're into Ubuntu. Setting up a GB10 workstation is quicker than any current Windows PC. DGX OS is also generally compatible with a lot of Linux software. Software like Firefox, LibreOffice, and VS Code work without issue.
The hard part is what comes next. NVIDIA GB10 workstations don't ship with a standardized GUI for downloading, using, and serving LLMs. That's going to take some effort on your part.

Screenshot: Matthew Smith
Fortunately, NVIDIA doesn't leave you to fend for yourself. The company provides a lengthy user guide and a number of "playbooks" with step-by-step instructions for installing common AI software like Comfy UI, OpenClaw, NemoClaw, LM Studio, vLLM, among others.
I went with my go-to, LM Studio. I first installed the LM Studio CLI. This could prove a bit difficult if you're not familiar with the Linux CLI, but the NVIDIA playbook on LM Studio is a good guide, and installation has only a few steps. You'll also need to download models; again, the NVIDIA playbook provides instructions for how to do this, and they're quite simple. Most of the setup time is spent waiting for models to download.
Speaking of models, I focused my attention first on Alibaba's Qwen3.5-35B-A3B and Gemma-4-26B-A4B. These are recently released mixture-of-expert models. I used a 4-bit quantization of Qwen3.5 and an 8-bit quantization of Gemma 4.
Big improvements in tool calling make a GPT-like experience viable
Qwen3.5-35B-A3B and Gemma-4-26B-A4B are excellent LLMs. They're great at coding, can reason through complex problems, and output clean copy (though I noticed Qwen3.5 was more verbose than the comparatively terse Gemma 4). But there's one particular capability that completely changes the game: tool calling.
Many of the most useful features found in ChatGPT and Claude stem from tool use. Want to search the web? That requires tool use. Want to read a document? Tool use. Want to execute code in a sandbox? Tool use. Unfortunately, this is where small LLMs stumble.

Screenshot: Matthew Smith
Qwen3.5-9B is a good example. This variant of Qwen3.5 is small enough to run the 4-bit quantization on a 16GB video card with some room left over for context, and it's good at generating text and code.
If you try to use it for web search via tools in LM Studio, though, it's not so hot. The tool calls often fail because the model doesn't know how to call the tool correctly. That makes it difficult to achieve a ChatGPT-like experience in LM Studio.
The DGX Spark and other GB10 workstations solve this by providing enough memory to easily load larger models. Qwen3.5-35B-A3B is part of the same model family as Qwen3.5-9B, but unlike its smaller sibling, it almost never fails tool calls. It's possible to have the LLM search the web, write to files, and perform command line operations reliably.
128GB offers plenty of room for context and models
Better tool calls are one half of the capability an NVIDIA GB10-powered AI workstation can offer. The ability to handle large amounts of context and multiple models is another.
As you've probably heard, AI models take up a lot of space in memory. The 4-bit quantization of Qwen3.5-35B-A3B is roughly 20.5GB, and the 8-bit quantization of Gemma-4-26B-A4B is roughly 26GB.
Those are big numbers. But they're not that big, right? Surely any laptop with 32GB of memory and a decent integrated GPU or NPU can handle it?
Unfortunately, the model isn't the only thing we need to load. We also need space for the model context—the store of all the prompts, replies, and files used in a session with the LLM (memory usage climbs because of the KV Cache or Key-Value cache). And that can take up a lot of space.
Many current local models, including Qwen3.6 and Gemma 4, can handle a context window up to 256,000 tokens. But if you actually make use of that context you'll find the amount of memory consumed increases. A model with around 30 billion parameters can require up to around 30-40GB depending on quantization. Larger models with larger context windows will require even more.
And what if you want to host multiple models? In that case, you need to have room for each model to be loaded into memory. Serving up Gemma-4-26-A4B by itself is not tough for an AI workstation with 128GB of memory. But if you want to serve Gemma-4-26-A4B alongside Qwen3.6 (or any other combo), you're going to need the extra memory.
NVIDIA Blackwell GB10's performance
In fact, the main hardware limitation of most AI workstations is not the memory but instead the available memory bandwidth and compute performance.
The NVIDIA GB10 found in the DGX Spark and similar AI workstations has a 256-bit memory interface that can provide up to 273GB/s of memory bandwidth. That's not bad, but most GPUs have a lot more. An NVIDIA RTX 5090 desktop video card, for example, has a 512-bit memory interface and provides up to 1.79TB/s of memory bandwidth. The RTX 5090 also has roughly 4x more shader units and 2x more tensor cores.
In practice, that means the GB10 can load very large models, but inference performance is rather slow.
The NVIDIA GB10 is rather good when it's serving up a smaller mixture-of-experts model. But if you want to serve a larger model, like Qwen3.5-135B, you can start to run into limitations. Even a 1,500-token reply can take a full minute to complete.
I also ran my tests starting with no prior context in the context window. An LLM slows as the context window fills up, so you can expect replies to take even longer if you're parsing through many documents or a large code base.
To be fair to the NVIDIA GB10, the speeds aren't that much worse than leading cloud models. Artificial Analysis states that OpenAI's GPT-5.4 typically delivers around 80 tokens per second, while Claude Sonnet 4.6 delivers about 50 tokens per second. The cloud models have an advantage in tokens-per-second performance but it's not a total blow-out.
Running an LLM locally might also prove more reliable. Anthropic, in particular, has suffered a lot of downtime in recent months as a surge in demand overwhelmed the company's compute infrastructure—and an LLM that's unavailable generates zero tokens per second.
Can you replace ChatGPT or Claude with local AI? Yes...but...
So, let's get back to the question at hand. Can you use an AI workstation to replace ChatGPT or Claude?
The answer is yes—though not without caveats.
A local AI workstation makes sense if you care about privacy, openness, reliability, or cost-per-token. It doesn't make sense if you need access to cutting-edge frontier models or don't have a use that justifies the upfront cost of a workstation priced at $4,500 to $6,000 (or more).
Still, I call this a win. A local AI workstation has situations where it's preferable to relying on an AI model in the cloud.
Fortunately, the quality of the related software and the available models have improved in recent months. Buying and using an AI workstation, like the DGX Spark, is now easy enough for anyone enthusiastic about PC hardware to understand, and useful enough to deliver most of the capability of a cloud model without relying on API access or a monthly subscription.
More from MC News
- Run AI Locally: The Best LLMs for 8GB, 16GB, 32GB Memory and Beyond
- Quantization Explained: Why the Same LLM Gives Better Results on High-End Hardware
- How to Use LM Studio to turn your PC into an AI Server
- Why VRAM and Memory Bandwidth are Key for Powering Local AI
- Keyboard 101: Intro to Computer Keyboards
- Fix It Yourself: Talking to iFixit on Why Repairable Tech Matters
- The Local LLM Your Laptop's Been Waiting For
- Gemma vs Qwen: Which Local AI is Best?
Matthew S. Smith is a prolific tech journalist, critic, product reviewer, and influencer from Portland, Oregon. Over 16 years covering tech he has reviewed thousands of PC laptops, desktops, monitors, and other consumer gadgets. Matthew also hosts Computer Gaming Yesterday, a YouTube channel dedicated to retro PC gaming, and covers the latest artificial intelligence research for IEEE Spectrum.






